Wednesday, 5 February 2020

FOSDEM 2020

My post-FOSDEM detox has started - despite preparing by reading some survival guides, I hadn't really fathomed the variety and quantity (and quality) of beer that would flow over four days.  On reflection however, the beer flow has been far exceeded by the flow of tech content and conversation.

On Thursday and Friday I attended the pre-FOSDEM MySQL Days fringe event, where there were two tracks of talks and tutorials on MySQL including sessions on :
 - MySQL Server simplification
 - MySQL replication tooling improvements
 - Configuring group replication
 - Troubleshooting group replication
 - Using DNS for loadbalancing and failover
 - Upgrading to MySQL 8.0
 - New hash join implementation
 - Indexing JSON arrays
 - Datetime types
 - Check constraints
 - New VALUES() syntax
 - Security-hardening MySQL
 - Document store
 - MySQL Analytics
 - MySQL Replication performance modelling
 - Machine learning for MySQL service automation
 - Using reduced durability modes
 - Benchmarking
 - Using Vitesse
 - Using InnoDB Cluster

There were sessions from Oracle, Percona, Planetscale, Facebook, TicketSolve, DBdeployer and Uber.

Naturally the highlights for me were the Friday sessions focused on MySQL Ndb Cluster including :


https://twitter.com/lefred/status/1223274289744547840


  • MySQL NDB 8.0 clusters in your laptop with DBdeployer - Giuseppe Maxia

    This was a great session from the Datacharmer Giuseppe, where he talked about DBdeployer, which is a tool for trying out different database software versions, configurations and topologies.  Giuseppe demonstrated how to use DBDeployer to setup two MySQL Ndb Clusters very simply, starting them in under 30 seconds and testing both the synchronous internal replication within each cluster and the asynchronous replication between them.

    If you want to experiment with MySQL Cluster then I think DBDeployer looks like the easiest and quickest way to get started.
https://twitter.com/lefred/status/1223204988148690946

 
  • SQL with MySQL Ndb 8.0 faster than your NoSQL allow - Bernd Ocklin

    This session was focused on one of Ndb's traditional strengths - performance.  Bernd presented an array of benchmarks showing that MySQL Ndb Cluster continues to be faster than the NoSQL products invented in response to the claim that 'SQL cannot scale'. 

    The presentation had lots of graphs and numbers showing linear scalability, hundreds of millions of reads per second from a single cluster, winning efficiency + performance comparisons on YCSB, scalability of parallel disk I/O and scalability of Ndb as a Hadoop metadata and small file store.

    Bernd then gave some insights into the unique architecture of Ndb, which allows it to achieve these numbers.

    Finally there were some more graphs and numbers :

    First looking at TPC-H query performance as data node internal parallelism scales, and showing how the query processing parallelism in Ndb allows a 2-node distributed (HA) Ndb setup to outperform a single node InnoDB on some queries.

    Next looking at DBT2 (TPC-C) scalability as # replicas and # NodeGroups were increased, and also looking at the behaviour of DBT2 when run using Optane memory for system scale.
https://twitter.com/lefred/status/1223222430623326208


  • Boosting MySQL Ndb Cluster & MySQL InnoDB Cluster with ProxySQL v2 - Marco Tusa

    Marco from Percona showed how having a layer of proxies in front of a cluster can simplify providing an HA MySQL service, smooth operations and allow new features not available in MySQL itself.  He laid out architectures for InnoDB Cluster and Ndb Cluster, and noted that Ndb cluster was the only cluster that could scale out writes. 

    He enthusiastically followed this up with numbers by showing how adding MySQL Servers to a cluster can allow it to scale beyond the limits imposed by a single MySQLD.

  • MySQL Ndb 8.0 Cluster tutorial - Frazer Clement

    In my session we stepped through installing, configuring, starting and using a MySQL Cluster, including looking at high availability features, push down joins, foreign keys, JSON, Binlogging, Synchronized privilieges, and online scale-out.

    The audience were generous with feedback and questions, complementing my mid-90's style use of a text file, and generally surprised at how easily they had a cluster running on their laptop, even when manually performing all the steps required.
https://twitter.com/lefred/status/1223255796802314240


After my tutorial, I was interested in locating and consuming a drink, and luckily the MySQL Community dinner was just starting in the event venue.  This was a very agreeable event, well attended by the wider community including colleagues from 'old MySQL' that I had not seen for over 10 years.  It is great to see that while there are differences of opinion, and competition, we still have more in common than not.
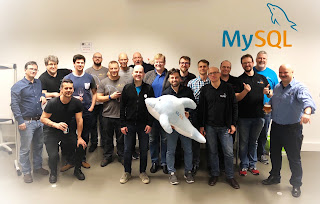
https://twitter.com/lefred/status/1223340364683251712


On Saturday the action moved to the FOSDEM conference itself, running in a University campus.  Despite looking at the program I had not quite appreciated the volume of tracks, sessions and experts that would be present and talking in the rooms and the corridors.  The MySQL developer room alone had 17 talks from across the community, one every half hour for eight and a half hours !

I spent most of my time here, but also attended some talks in the other tracks, including some interesting performance talks in the Software Defined Networking room including a nice one on vectorising packet processing in DPDK.  Unfortunately I was unable to attend the run a mainframe on your laptop session in the Retrocomputing room, but luckily everything was being streamed, and the videos are being uploaded here.  While wandering around the University campus I stumbled upon a bar and tried some of the (open-source?) FOSDEM beer.

I will not bore you by enumerating all of the sessions, following beers and conversations, but I can definitely recommend reviewing the schedule and viewing some of the captured videos to get a bit of the experience for yourself.  Even better, if this sounds like your sort of thing, why not see if you can find a way to attend yourself, in 2021?

Many thanks to lefred for organising, running, presenting, photographing and tweeting across all the events.

Tuesday, 28 January 2020

MySQL Cluster at FOSDEM 2020


Tomorrow I depart for Brussels, where FOSDEM 2020 is taking place this weekend.

This will be my first FOSDEM and I have heard many good things about it - there are quite a few FOSDEM survival guides online which give a sense of what it is about.

As part of the main FOSDEM event there is a MySQL, MariaDB and friends developer room, with sessions from across the MySQL ecosystem.  Additionally there is also a Databases main track and a PostgreSQL developer room as well as a wide variety of other tracks and developer rooms.

As if that were not enough, there is also a FOSDEM Fringe, before, during and after FOSDEM itself.  This year MySQL are holding a two day fringe event called pre-FOSDEM MySQL Days on Thursday and Friday, where there are two tracks, with over thirty sessions from the MySQL community team, engineers, product managers, customers, contributors and others.

MySQL Cluster is well represented on Friday with four talks from Bernd Ocklin, Giuseppe Maxia and Marco Tusa about using the new MySQL Cluster 8.0.  Later on Friday afternoon I will be running a tutorial on MySQL Cluster 8.0, covering configuration, setup, and looking at some of the existing and new features.

If you are going to be there then maybe we will see each other.  If not then maybe you should try to get there next year?


Wednesday, 14 October 2015

MySQL Cluster at Oracle OpenWorld 2015

It's Oracle OpenWorld time, and MySQL Cluster will be in San Francisco again along with the rest of the MySQL team. 

The session agenda is online, but can be tricky to navigate given the breadth of the conference, but it's possible to narrow down to those sessions in the MySQL track.

From a MySQL Cluster perspective, there two conference sessions from the Cluster development team, a Hands-On Lab from our Cluster Support team and most exciting, a conference session from some real-world users at NEC.

200 Million QPS on Commodity Hardware—Getting Started with MySQL Cluster 7.4
[CON2178]

Frazer Clement, MySQL Cluster Technical lead, Oracle

Bernhard Ocklin, Director MySQL Cluster Engineering, Oracle

Do you have performance demands that a database can’t scale to meet — especially one as simple as MySQL? And if it were even possible, would it require top-of-the-range servers and storage? We previously demonstrated that MySQL Cluster could scale to 1 billion writes per minute, and MySQL Cluster 7.4 exceeded 200 million queries per second (QPS), all with open source software running on commodity servers. Discover how MySQL Cluster achieves this scalability while also delivering in-memory performance, 99.999 percent availability, active-active update-anywhere geographic redundancy, ACID transactions, and both SQL and NoSQL access. Finally, this session offers some tips on getting MySQL Cluster up and running so that you can try it out for yourself.
Conference Session

Monday, Oct 26, 2:45 p.m. | Moscone South—262

Fully Elastic Real-Time Services with MySQL Cluster
[CON4772]
Bernhard Ocklin, Director MySQL Cluster Engineering, Oracle
In this session, learn how the MySQL Cluster in-memory real-time engine brings together the best of both worlds—SQL and NoSQL. It scales from a single Raspberry Pi to systems on hundreds of servers.  MySQL Cluster powers networks for more than a billion mobile phone users worldwide and serves massive multiplayer online gaming back-ends. The MySQL Cluster architecture allows the addition or removal of nodes in seconds without interrupting service. It adopts to capacity demands making resources available instantaneously and when needed. Its native Node.js platform and connectors for Java make it easy to write real-time web applications in the cloud. This sessions guides you through common architectures and a use case for elastic MySQL Cluster cloud deployments.
Conference Session
Tuesday, Oct 27, 11:00 a.m. | Moscone South—262

MySQL Server and MySQL Cluster at India’s Financial Inclusion Gateway Service
[CON3846]
Shrestha Anishman, Engineer, NEC Corporation
KEIJI ENDO, Staff, 日本電気株式会社
太地 岩田, Manager, 日本電気株式会社
NEC is developing India’s financial inclusion gateway service utilizing MySQL Server and MySQL Cluster. To handle the massive, business-critical financial transactions involved in this project, NEC has conducted deep, detailed research on internal architectures and behaviors of MySQL products. This session explores use cases of MySQL Server and MySQL Cluster in India’s financial inclusion gateway service, and explains how to select appropriate software and optimize systems architecture with methods of software architecture analysis at NEC.
Conference Session
Tuesday, Oct 27, 5:15 p.m. | Moscone South—250

Get Started with MySQL Cluster 
[HOL3348]
Benedita Vasconcelos, Principal Technical Support Engineer, Oracle

Attend this hands-on lab to learn the basics of MySQL Cluster—when to use it, when not to use it, and how to install, configure, administer, and access it. MySQL Cluster is a write-scalable, real-time, ACID (atomicity, consistency, isolation, and durability)-compliant transactional database combining 99.999 percent availability with the low TCO of open source. Developers and DBAs attending this session have the chance to familiarize themselves with MySQL Cluster and get a better understanding of how to use it to meet the database challenges of next-generation web, cloud, and communications services with uncompromising scalability, uptime, and agility.
HOL (Hands-on Lab) Session
Thursday, Oct 29, 9:30 a.m. | Hotel Nikko—Peninsula (25th Floor)


There are many other relevant talks from the MySQL team covering Server improvements, Replication improvements, OpenStack integration, Customer success stories etc.

Outside the MySQL track, there are sessions covering the breadth of Oracle products and services.  Despite developing the world's most popular Open Source Database, Oracle still puts some effort into developing older DBMS products :).  I will be interested to hear of the latest advances there.

However the main attraction of a conference like this is meeting people and getting to talk face to face.  If you don't have an OOW pass, but want to mix with the MySQL crowd then please come to the MySQL Community Reception on October 27th.  You can pre-register to avoid any queueing.

See you there!

Thursday, 6 March 2014

Reports exaggerated

I've been letting the blog rest recently, and not so recently as well.  The problem is not a lack of subjects, but a lack of time to do them any justice.  However it is quite sad to see that my last entry was in September 2012, so it is time to post again.

Of late I have been pondering what I have to say about :
  • Distributed MVCC and write-scaling
  • Different approaches to eventual consistency with replicated RDBMS
  • Various MySQL Cluster related topics
  • Various general rambling and unstructured topics
However, these will take some time to percolate and calcify.

In the meantime here are some things I have found interesting recently :
  • Learn You Some Erlang for Great Good
    I actually rediscovered this online book after watching some Joe Armstrong + Erlang videos, after watching some spoof video about bringing Erlang up to date.  All recommended  Erlang and Ndb Cluster share some Plex heritage, which can still be seen in their architectures today.  Since Plex, Erlang has mated with Prolog, and Ndb Cluster was involved in a car crash with C++.
  • HyperDex + Hyperdex Warp
    Something I discovered last year from Emin Gün Sirer's blog and have returned to since.  There are a number of nice ideas combined here (chain replication, value dependent chaining, hyperspace hashing, subspaces).  My favourites are the concept of 'spurious coordination' and their solution w.r.t. transaction consistency : ordering the route of the optimistic 'distributed commit' based on the affected keys.  I guess we need more independent analysis and evaluation to understand the strengths and weaknesses of these techniques.
  • Kronos
    This is a distributed HA 'event ordering system' from the same Cornell HyperDex team.  Thinking about distributed MVCC led me to thinking about efficiently maintaining a distributed partial ordering of events while avoiding 'spurious coordination'.  Kronos is an attempt to solve part of that problem in a kind of abstracted SOA way.  There is some nice detail in the paper about their dependency graph traversal optimisations, and how dependencies are immutable once discovered, so can be cached, replicated for read scale-out etc.  This could be a great systems building block.
  • Systems Performance book
    I am slowly reading this doorstop book from Brendan Gregg, an ex Solaris kernel engineer at Sun, now at Joyent.  It contains a great amount of recent practical information about Linux + Solaris performance analysis and optimisation.  Unix performance tools have always been a little opaque to me, with very little of how-to-approach a performance problem ever being documented.  This book covers many old and new tools, but also includes rare information on how to analyse problems with these tools, rather than just syntax and units of values returned.  Perhaps even better is his supreme confidence about tackling and solving any performance problem that foolishly catches his eye.  I guess that comes from experience, but maybe a little can be conveyed to his readers by this book.
  • Google Spanner, Galera Cluster, MoSQL, RAMCloud, NuoDB, OpenReplica
    Different approaches, ideas, hidden tradeoffs, strengths and weaknesses!
One of my favourite discoveries was this quote attributed to Charles Babbage :
"On two occasions I have been asked 'Pray, Mr. Babbage, if you put into the machine wrong figures, will the right answers come out?'
I am not able rightly to comprehend the kind of confusion of ideas that could provoke such a question." 
Strange how often this response has been on my lips since !